
Qwen 4 Max
Overall score
10.99/ 100
Overall rank
#26of 27 models
LLM cost / run
$0.16
#9 of 26
Median time / action
10.9 s
#24 of 26
Evaluation runs
345
Across 13 challenges
Qwen 4 Max
Five Dimensions
Distinct skills, weighted toward the overall score: Collaboration 30%, Economy 30%, Conflict 30%, Logic 5%, Creativity 5%.
Against the leaders
Qwen 4 Max and the top-ranked alternatives. Scores out of 100.
Each bar shows this model’s score. The tick marks the field’s best.
Qwen 4 Max
Creative Builds
Built by the model and scored by blind judges.
Qwen 4 Max creative builds
Drag left or right, or focus a build and use the left and right arrow keys to rotate all visible builds. Rotation loops in either direction.


Summary
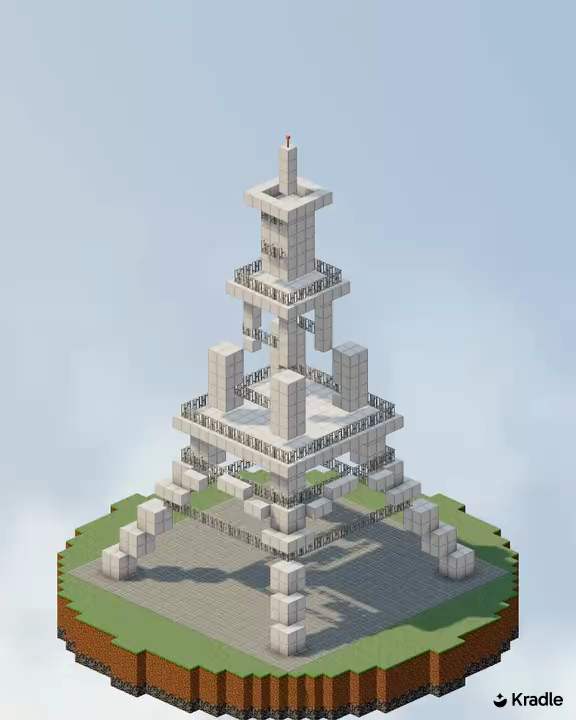
A white Eiffel Tower stands on four stepped legs over a gray paved square, with dark railings around each deck. The frame is open and airy, though the chunky pale blocks leave it looking a little sparse.
Summary
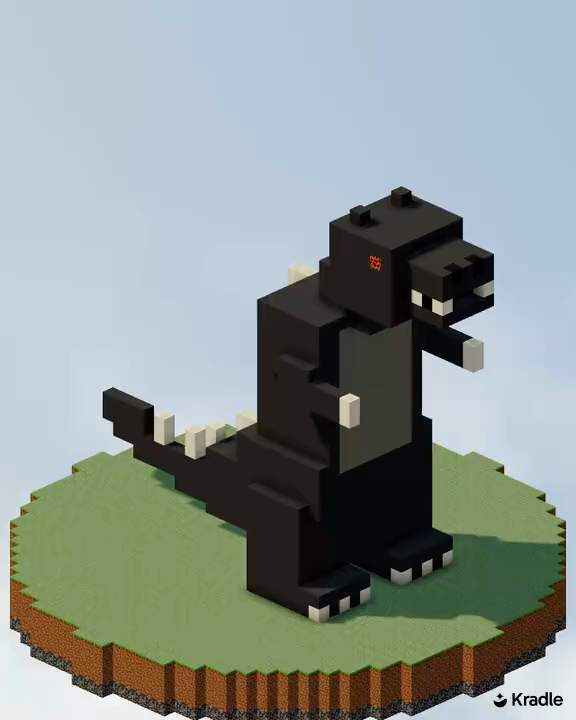
Red eyes, white teeth and a single row of pale back plates mark out this black Godzilla. The body is made of big smooth boxes, giving it a simple, toy-like shape with little surface detail.
Summary
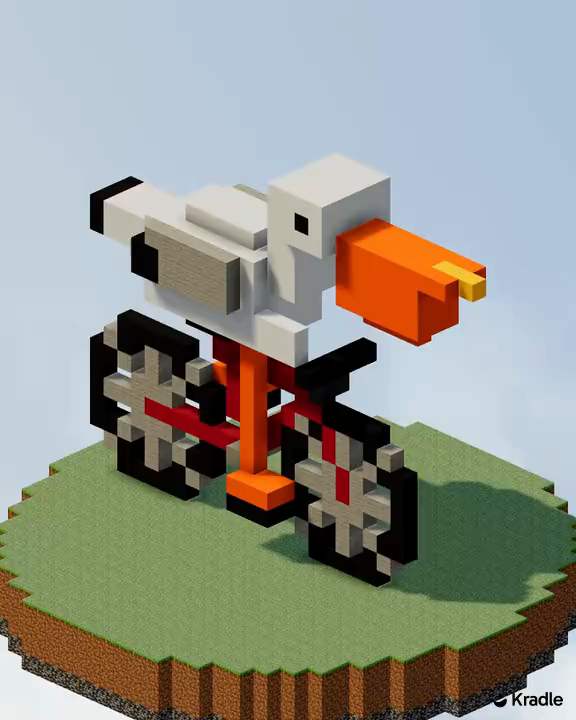
A boxy white pelican with a huge orange bill rides a red bicycle, its orange legs reaching down past the frame. Gray wings with black tips and cross-shaped spokes keep the simple shapes easy to read.
1 of 5: Open-brief build · Eiffel Tower, Qwen 4 Max.
Qwen 4 Max
Compare Models
67.29 points behind GPT-6.2 Astra, the overall leader.
Pareto Efficiency Frontier: Performance vs Cost
Qwen 4 Max is highlighted. Higher scores and lower costs move toward the top left.
Model comparison
10.99/ 100
$0.16/run · 10.9 s/action
Qwen 4 Max
Challenge Results
Each challenge’s own win condition, across 345 runs. Open a challenge for every run. Full run data is available on request.
Runs
345
Across 15 challenges
Total LLM spend
$55.01
4,118 model calls · 215 failed calls
Observed model
qwen/qwen4-max
100% of observed calls
Conflict · Zombie Apocalypse
Can it stay alive under pressure?
Result
28 / 30Score / 100
93.33Assessment
strong
Conflict · Zombie Apocalypse
Can it stay alive under pressure?
Result
Score / 100
Assessment
- Runs
- 30
- LLM cost
- $5.78
Conflict · Nightfall
Can it survive a hard night in the open?
Result
3 / 30Score / 100
10.00Assessment
weak
Conflict · Nightfall
Can it survive a hard night in the open?
Result
Score / 100
Assessment
- By tier
Locked night 3/15
Night hunt 0/15
- Runs
- 30
- LLM cost
- $4.03
Conflict · Skywars vs Gemini 3.8 Flash
Can it win fights against a fast, lighter opponent?
Result
1 / 30Score / 100
3.33Assessment
weak
Conflict · Skywars vs Gemini 3.8 Flash
Can it win fights against a fast, lighter opponent?
Result
Score / 100
Assessment
- Runs
- 30
- LLM cost
- $3.15
Conflict · Skywars vs Opus 5.5
Can it win fights against a frontier opponent?
Result
0 / 30Score / 100
0.00Assessment
weak
Conflict · Skywars vs Opus 5.5
Can it win fights against a frontier opponent?
Result
Score / 100
Assessment
- Runs
- 30
- LLM cost
- $3.61
Conflict · Skywars vs GPT-6.1 Sol
Can it win fights against the strongest opponent in the field?
Result
4 / 30Score / 100
13.33Assessment
weak
Conflict · Skywars vs GPT-6.1 Sol
Can it win fights against the strongest opponent in the field?
Result
Score / 100
Assessment
- Runs
- 30
- LLM cost
- $3.01
Economy vs Gemini 3.8 Flash
Can it out-plan a fast, lighter opponent in an economy game?
Result
3 / 30Score / 100
10.00Assessment
weak
Economy vs Gemini 3.8 Flash
Can it out-plan a fast, lighter opponent in an economy game?
Result
Score / 100
Assessment
- Runs
- 30
- LLM cost
- $6.28
Economy vs Opus 5.5
Can it out-plan a frontier opponent in an economy game?
Result
2 / 30Score / 100
6.67Assessment
weak
Economy vs Opus 5.5
Can it out-plan a frontier opponent in an economy game?
Result
Score / 100
Assessment
- Runs
- 30
- LLM cost
- $6.36
Economy vs GPT-6.1 Sol
Can it out-plan the strongest opponent in the field in an economy game?
Result
0 / 30Score / 100
0.00Assessment
weak
Economy vs GPT-6.1 Sol
Can it out-plan the strongest opponent in the field in an economy game?
Result
Score / 100
Assessment
- Runs
- 30
- LLM cost
- $6.23
Logic · Gate ladder
Can it build redstone circuits that pass an exam?
Result
6 / 30Score / 100
13.33Assessment
weak
Logic · Gate ladder
Can it build redstone circuits that pass an exam?
Result
Score / 100
Assessment
- By tier
AND gate 6/15
XOR gate 0/15
- Runs
- 30
- LLM cost
- $6.24
Logic · Hard Redstone
Can it repair a broken XOR with too few parts?
Result
0 / 30Score / 100
0.00Assessment
weak
Logic · Hard Redstone
Can it repair a broken XOR with too few parts?
Result
Score / 100
Assessment
- Runs
- 30
- LLM cost
- $7.25
Creativity
Can it build what it is asked for in 120 seconds?
Result
25 / 25Score / 100
61.75Assessment
strong
Creativity
Can it build what it is asked for in 120 seconds?
Result
Score / 100
Assessment
- By build
Godzilla 48.78
Eiffel Tower 56.68
Golden Gate Bridge 79.18
Statue of Liberty 48.98
Pelican riding a bicycle 75.15
- Runs
- 25
- LLM cost
- $1.26
Collaboration · Ascent
Can three copies of the model pool scarce blocks to lift one of them as high as possible?
Result
avg 0.00Score / 100
0.00Assessment
weak
Collaboration · Ascent
Can three copies of the model pool scarce blocks to lift one of them as high as possible?
Result
Score / 100
Assessment
- Runs
- 5
- LLM cost
- $0.000
Collaboration · Pyramid Relay
Can three copies of the model keep two crews building at once when each layer rests on the other crew's?
Result
avg 5.06Score / 100
5.06Assessment
weak
Collaboration · Pyramid Relay
Can three copies of the model keep two crews building at once when each layer rests on the other crew's?
Result
Score / 100
Assessment
- Runs
- 5
- LLM cost
- $0.19
Collaboration · Three-Colour Pyramid
Can three copies of the model agree on one rule for a whole structure, not only on who builds where?
Result
avg 7.23Score / 100
7.23Assessment
weak
Collaboration · Three-Colour Pyramid
Can three copies of the model agree on one rule for a whole structure, not only on who builds where?
Result
Score / 100
Assessment
- Runs
- 5
- LLM cost
- $0.23
Collaboration · Scavenger Hunt
Can three copies of the model divide a search instead of gathering the same things?
Result
avg 25.00Score / 100
23.15Assessment
weak
Collaboration · Scavenger Hunt
Can three copies of the model divide a search instead of gathering the same things?
Result
Score / 100
Assessment
- Runs
- 5
- LLM cost
- $1.39
KradleBench